AI Agents
Set an AI agent (an AI task that works through a goal on its own, using Aegis's own read-only lookups) one compliance or risk question, then read its answer and its working from the run history.
The AI Agents page handles the longer, multi-step questions that are awkward in a back-and-forth chat. You describe one goal up front — for example, “list the NIS2 (a European cybersecurity law) controls we have marked as not implemented” — and a background worker takes it from there. The agent forms a thought, calls one of a small set of read-only lookups over your records, reads what comes back, and repeats. Each of those think–act–read cycles is one iteration. The run, its iterations, the tokens it used and its final answer are kept in a history you can reopen at any time.
This is assistance, not automation of decisions. An agent reads and drafts; it cannot change a policy, a risk or a compliance record. A person reads the output and decides what to do with it.
Who uses it
The page requires Contributor or above, and the AI module must be switched on for your organisation.
-
Viewer — no access. The
AI Agentsentry does not appear in the sidebar, and opening/ai/agentsdirectly sends you to the/unauthorizedpage. - Contributor — can start runs, read the history of their own runs, and cancel a run that is still queued or running.
- Manager — the same as Contributor, and reads everyone's runs, not only their own.
- Admin — the same as Manager, and also controls the AI settings that switch AI assistance on or off.
If you hold Contributor or above and the entry is missing, the AI module has not
been enabled for your organisation. If the entry is there but the history
reports
Failed to load agent runs with a Try again button, AI
assistance itself is off or unavailable; see
Settings.
Starting a run takes two rights: the right to start agent runs and the
organisation-wide right to run AI actions. Contributors and above hold both by
default. If your administrator has withdrawn either one from you, the
Start New Agent Run card is not shown at all and the page opens on
Run History alone, so you can still read your runs.
What's on this screen
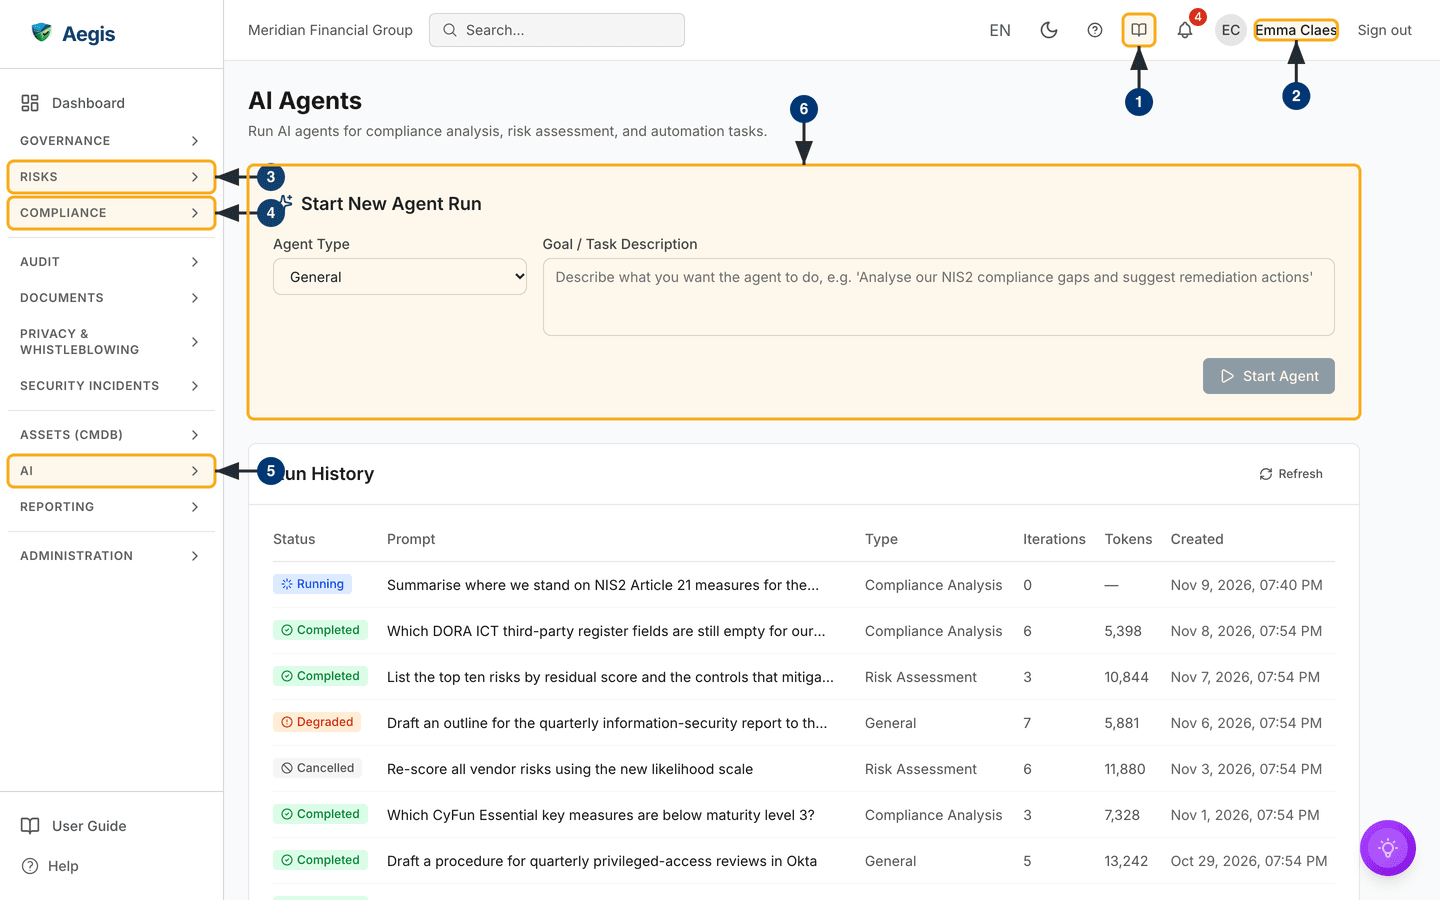
The page is a single column: the heading AI Agents above the line
“Run AI agents for compliance analysis, risk assessment, and automation
tasks”, then two stacked cards. The page itself has no filter bar and no
search box — the search field in the top bar is the app-wide one, and it does
not search run history.
-
Start New Agent Run— the first card. It holds a narrowAgent Typedrop-down on the left, which opens onGeneral, and a widerGoal / Task Descriptionbox beside it, with placeholder text showing an example goal. AStart Agentbutton sits at the bottom right of the card and stays disabled until the goal box has text in it. -
Run History— the second card, with aRefreshcontrol at its top right. Below that is a table of runs, newest first, with the columnsStatus,Prompt,Type,Iterations,TokensandCreated. A long prompt is cut short with an ellipsis to keep each row on one line. Every row is clickable and opens a detail window; the prompt text itself is a button, so you can also reach a run with the keyboard.
The captured screen shows the seeded demonstration history for a fictional
organisation. A blue
Running run sits at the top with 0 under
Iterations and a dash under Tokens, because neither is
written until the run ends. Below it are green Completed runs of
the Compliance Analysis, Risk Assessment and
General types, each with a handful of iterations and several
thousand tokens, one orange Degraded run and one grey
Cancelled run. Your own history will differ, and on a new
organisation it is empty.
Before you start a run, check the ground the agent will read. The numbers match the figure.
- Select the book icon in the top bar. The User Guide opens at the chapter for the screen you are on, so you can keep these steps beside the page.
- Check the name at the top right. Every run you start is recorded against this account, and as a Contributor it is your own runs that the history shows you.
-
Open
RISKSin the sidebar and confirm the risks you want examined are recorded. ARisk Assessmentrun can only reason over risks already in the register. -
Open
COMPLIANCEto check the frameworks and controls aCompliance Analysisrun will read. -
Use the
AIgroup to come back toAI Agents, or to move to the other AI pages while a run is going. -
Go to the
Start New Agent Runcard at the top of the page. Its controls are covered step by step in the next section.
Start an agent run
-
Open
Agent Typeand pick the framing for your question:Compliance Analysis,Risk AssessmentorGeneral. The type sets the instructions the agent works under — Compliance Analysis leans towards framework controls and evidence, Risk Assessment towards the risk register. -
Click into
Goal / Task Descriptionand write what you want in plain language. A precise goal — “identify which controls we have marked not implemented and suggest evidence that would close them” — gives a far better result than “check compliance”. TheStart Agentbutton becomes active as soon as you type. -
Select
Start Agent. The button changes toStarting…with a spinner, the form clears back toGeneral, and the history reloads with your new run at the top. If the run could not be created, a redFailed to start agent runmessage appears directly above theStart Agentbutton and your goal stays in the box. -
Watch the
Statuscolumn. A new run starts asQueuedand moves toRunningonce the worker picks it up. Nothing blocks while it runs, so you can leave the page and come back. -
Select
Refreshat the top right ofRun Historyto reload the table in place; the icon spins while it loads. Nothing polls automatically, so this is how you follow a run in progress.
Starting a run enqueues a background job, which the worker takes in turn. A
long wait in
Queued usually means the worker is busy with an earlier run or
has restarted. If it never moves, ask your administrator to check the
worker.
What the statuses mean
| Status | What it means |
|---|---|
Queued |
Submitted and waiting for the background worker. |
Running |
The agent is reasoning and calling lookups. The badge icon spins,
but
Iterations and Tokens stay at their
starting values — both are written once, when the run finishes.
|
Completed |
Finished with an answer that was grounded on at least one lookup of your records. |
Degraded |
Finished, but the agent never successfully read your own records. The answer is a generic framework, not an analysis of your data — read it as background reading only. |
Failed |
The run hit an error it could not recover from. The detail window shows the error. |
Cancelled |
Stopped before it finished, so no answer was produced. |
Degraded is deliberate honesty rather than a fault: an ungrounded
answer is flagged instead of being presented as a green success, and opening the
run repeats the warning in words.
Read a run and act on the answer
This edition has no capture of the run detail window; the steps describe what you will see.
-
Click anywhere on a row in
Run History, or tab to its prompt and press Enter. A window titledAgent Runopens over the page, with the status badge and the agent type — the same label as in the table, such asCompliance Analysis— along the top. If the run cannot be fetched, the window showsFailed to load run details.with aTry againlink. -
Read the
Promptsection — the full goal as you submitted it, not the truncated version shown in the table. -
Read the
Resultsection below it — the agent's final answer as formatted text. When the agent answers with a structured data block rather than prose, it is shown indented as it was written, and an answer too long to store ends with[answer truncated]. A degraded run shows an orange notice above this section, beginning “Grounding unavailable” and explaining that the answer is a generic framework, not an analysis of your records. A run that recorded an error gets a redErrorsection under the answer; on a failed run with no answer that section is all there is. -
Scroll on to
Tool calls— the heading carries the number of calls, as inTool calls (6), and the list below it is the agent's working: each lookup in turn, with its name and an outcome label (Success,Error,TimeoutorInvalid input), theArgumentsit was given, and underResultwhat came back — or, for a failed lookup, theErrorit returned. A lookup that left nothing behind readsNo result recorded for this call.This is how you check whether an answer rests on your data. A run that called nothing has no such section. -
Use the controls at the foot.
Copyputs the answer on your clipboard for completed and degraded runs. Under the answer itself,Save as recordkeeps the output as an AI insight linked back to this run, andCreate action itemopens a small form — the description arrives prefilled with the whole answer and the title with the words “Create action item”, which you replace with a real title — which needs permission to create action items. ACreate work itemscontrol appears beside them only for people who can create roadmap programmes. These controls under the answer appear only on completed and degraded runs.
Cancel a run
-
Open the run from the history table while it is still
QueuedorRunning. -
Select
Cancel runat the foot of the window. The control only appears for those two statuses and only for people who hold the right to start agent runs, so it is absent on a finished run. A Contributor can cancel only their own runs; Managers and Admins can cancel anyone's. -
The button shows
Cancelling…, the messageAgent run cancelled.appears, the status becomesCancelledand the history behind the window reloads. If the cancel is refused, the message readsCould not cancel the agent run.and the run carries on. The agent checks between iterations, so it stops before spending anything on the next one, though a cycle already in flight finishes first. A run cancelled while still queued is never started.
When the history is empty
On a new organisation the lower card shows a sparkle icon, the heading
No agent runs yet, and a line inviting you to start your first run
by describing a compliance task — the form for that sits in the card above.
Starting a run replaces the message with the table. The card holds twenty runs
at a time; beyond that a pager appears under the table with the range of runs
shown (for example Showing 1–20 of 34 runs),
Previous and Next controls and a
Page 1 of 2 marker.
The AI assist
Each run from this page is a reasoning loop with a ceiling of eight cycles. The agent is given read-only lookups over your own records — counts by type and status, risk analytics, framework coverage, a posture summary, listings and single records, and a search of your evidence — plus a regulation lookup, a freshness check, a claim check and, where one is configured, a web search. It has no tool that can write anything, so a run can never alter your records.
Reaching the cap does not throw the work away: a partial answer written at the
last cycle is kept as it stands. Only when the loop returns nothing usable at
all — a blank answer, or an error part-way through — does Aegis fall back to a
single reply made without any lookups. That fallback answer is ungrounded by
construction, so the run is marked Degraded.
Agent runs are recorded in your AI usage history but are not billed against your AI credits.
The agent gathers and drafts; you decide. A run reporting “no gaps found” has told you only that it found none with the lookups it made — not that your compliance position is sound.
Tips and limits
- Read the output critically. The model can state wrong facts with confidence, so check it against the source records before any of it reaches a binding compliance document.
- Check the tool calls before trusting a number. If the working shows no lookup of your data, treat the figures as unverified.
- Large questions may be summarised rather than exhausted. A goal spanning hundreds of risks can return a partial result: both the iteration cap and the model's context have limits.
- Runs can take minutes. The token count gives a rough sense of how much reasoning went into one.
- A submitted run cannot be edited. If the type or goal was wrong, cancel it while it is still queued and start a fresh one.
- Managers and Admins see every run in your organisation, not only their own, and this version has no filter or search here. Write goals a colleague would be comfortable reading.
Where this connects
- The AI assistant — the conversational counterpart, better suited to quick questions than to one long goal.
- Action items — where an answer goes when you turn it into tracked work from the run detail window.
- Risks, Compliance frameworks and Evidence — the records the lookups read.
- Audit log — where activity across Aegis, including AI use, is recorded.